Skip to content
How much to read

I build AI products people actually use, and I measure whether they work.

Looking for AI product manager roles.

Two are in daily use: a revision tool that answers medical exam questions out of nine textbooks and cites the page, and a ledger running a dental clinic behind an eval suite that fails the build.

Temenos
Software engineer, 3.5 years. Delivered the first client go-live on IBOR, for HSBC.
IIT Kharagpur
MBA, Vinod Gupta School of Management.
Optum
Product management intern, summer 2023.
Hexaware
Business development, selling AI-led delivery.

By day I sell AI-led delivery into enterprises, which is a weekly read on what buyers actually fund.

Two products in daily use

Everything below is written at three lengths.

30 sec
The short version: what he built, and whether it worked.
3 min
Adds why each decision was made, and the rules behind them.
Deep
Everything, including the working and what went wrong.

EaseMySemester

2026

Revision for the hour before a medical exam. It answers every question out of nine textbooks, cites the page, and declines rather than guesses.

34 of ~50students in the batch moved to v2, which has never been marketed
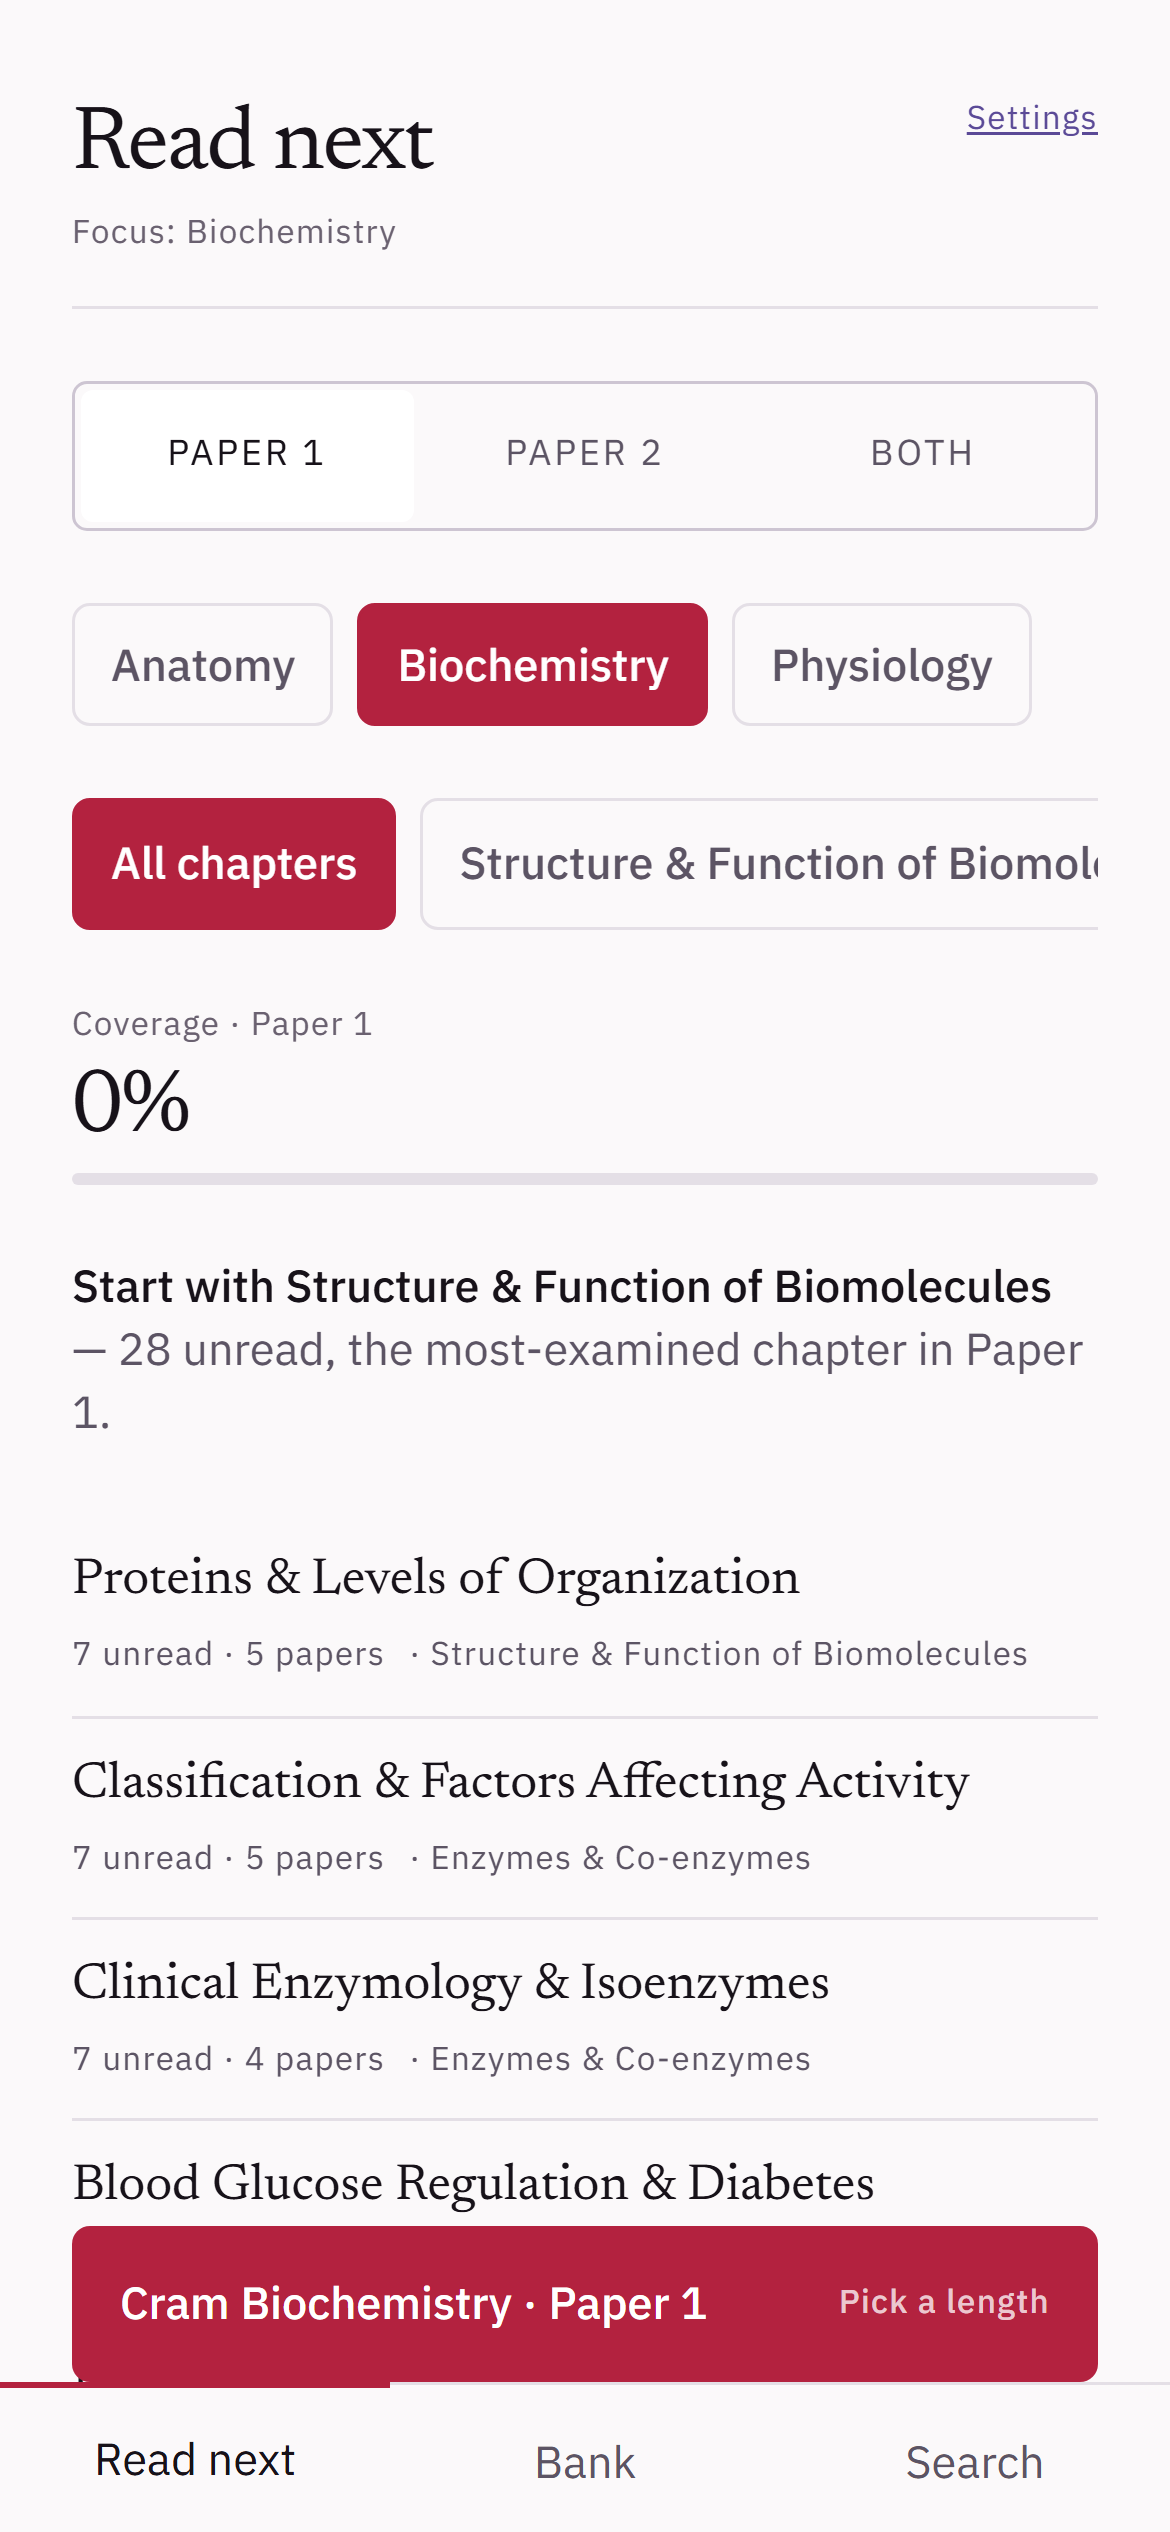
v2 on a phone, open on Read next: the paper being sat, the coverage so far, and a named chapter to start with, 28 unread and the most-examined in Paper 1.
Decision
Built for the hour before the paper, not the term.Build for the hour before the paper, not the term. Exam night won, and most of v1's structure went with it.
Refused
No signup, no paid tier, no ingestion pipeline.No public signup, no ingestion pipeline, no paid tier. Loading PDFs stays an offline job I run myself.
The number
809 questions answered out of nine textbooks, each citing its book and pages. 82, or 10.1%, decline rather than guess, nearly all multi-part questions with one unsourced sub-part. Corpus or retrieval, I have not separated which.
Still open
Whether the 82 answers that still decline are the corpus running out of material or my retrieval running out of ambition, which I have not yet separated. And whether removing the paywall buys the daily habit I am betting it buys, which I will not know until the semester starts.
What it proves
  • Cutting scope as I learned what the thing was for. v2 dropped the self-rating flow, the six-level browse tree as the front door, and question-level prediction, and I took out the paywall that six people were already through.
  • An answer feature that cites the book and the pages it was built from, and declines rather than guesses when the corpus does not cover the question.
  • Reporting the prompt change that improved one decline rate and tripled another, rather than the half of it that moved the right way.

v1, the version six students paid for, is kept as an appendix, with the measurement that replaced it.
Clarity

2026

A finance ledger running a dental clinic. The model writes up the month in plain words; typed code computes every number, and a gate drops any figure it cannot trace.

100 of 100eval cases pass, and the build fails if they stop

The first full run passed 86. What failed, and the fix, are in the case study.

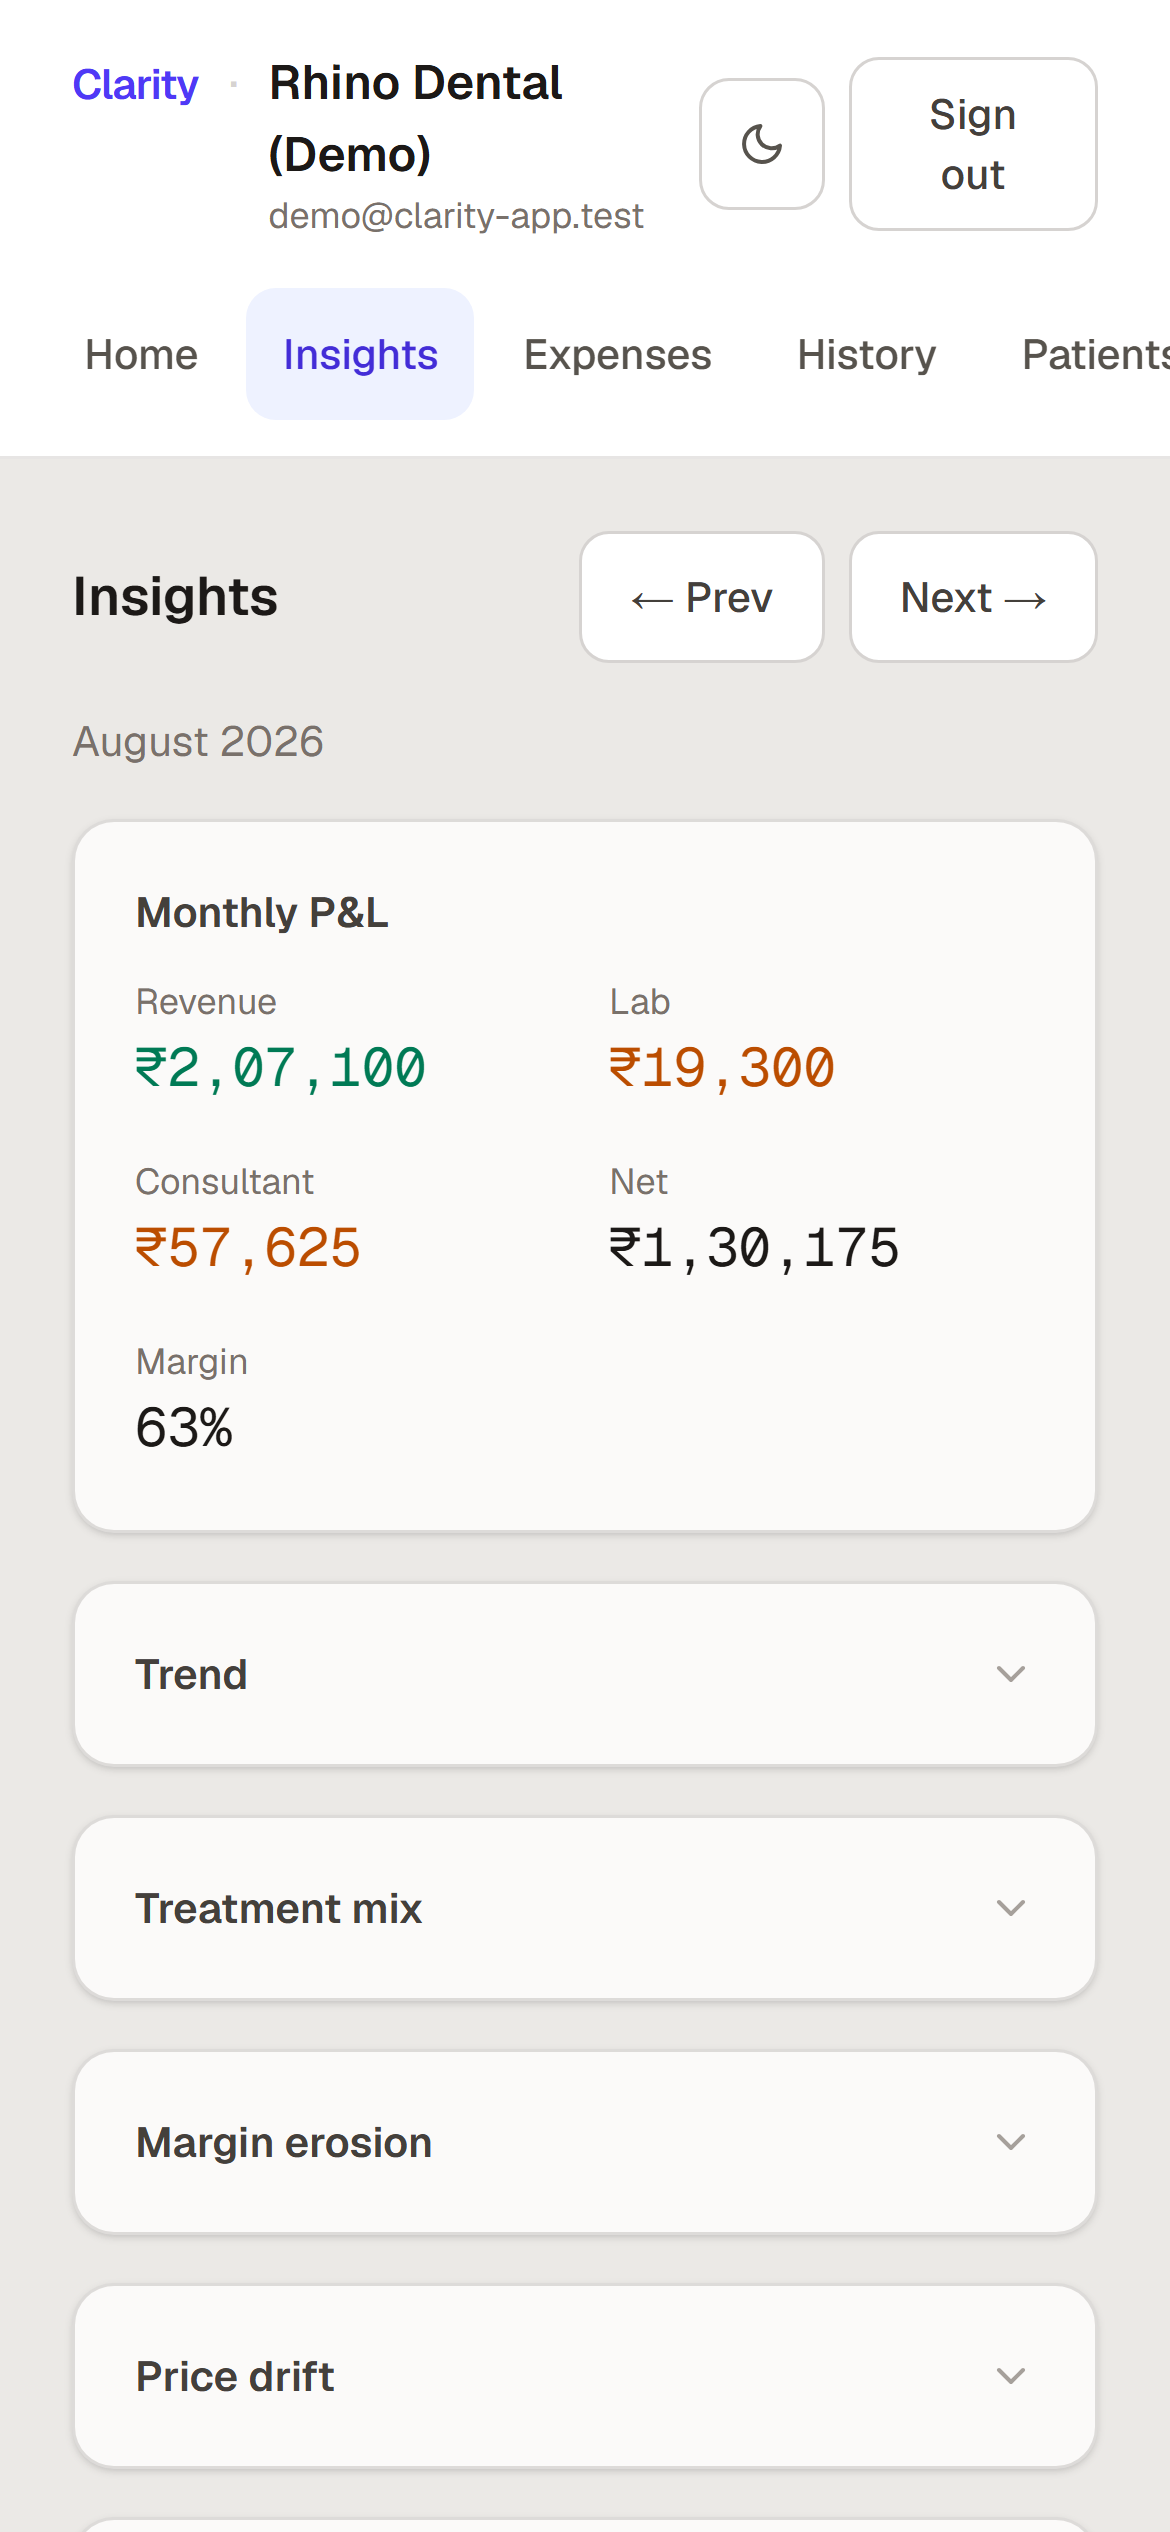
Insights for August 2026 on a phone: revenue, lab, consultant, net and a 63% margin, above the sections the narration is written from.
Decision
The model narrates; code computes every number.The model narrates and typed code computes. A numeral it cannot trace back to a source does not reach the screen.
Refused
Three things he asked for that I did not build.The tone scorer never gates a release, the payment QR automation stays unbuilt, and the keyboard shortcuts he told me he does not use are coming back out.
The caveat
The first run scored 86 and caught a real defect. The tone judge is deliberately left non-blocking.
Still open
Whether the narration can be served off my own hardware instead of a cloud API, and how little it can regenerate before the dentist stops trusting that what he is reading is current. On the rebuild, what a drifting recall interval actually means: the interview that produced the scope left it undefined, and it is the difference between a useful nudge and a nagging one.
What it proves
  • An LLM feature where typed code computes every figure and the model is architecturally forbidden from arithmetic, policed by an offline gate that discards the entire narration if one numeral cannot be traced to its source.
  • A 100-case eval suite that fails the build, with the tone judge deliberately left non-blocking, because a subjective score is the wrong instrument to hold a release hostage to.
  • Retiring the project's own headline metric after one user conversation showed it was comparing two different jobs.

I know when not to use a model.

Don't reach for a model where plain code is better.

Plain counting beat my own tuned weights on a year it had never seen, so counting shipped. In Clarity, typed code computes every figure and the model never does arithmetic. How it was measured

  1. Plain counting7.67
  2. The best weights a sweep could find7.33
  3. My own hand-tuned weights6.00
Topics recalled in the top ten, scored on an exam year the ranking had never seen. Counting shipped.
  1. Work out how I'd know it worked, before building it.

    The benchmark runner existed before a single retrieval setting had been tuned.

    Semantic Search

  2. Never let the thing that built it be the thing that grades it.

    A second model, with no tools and the sources given inline, checks every page the first one writes.

    Wiki Pipeline

  3. Believe the person using it over my own reasoning.

    I retired Clarity's own headline metric after one conversation showed it was comparing two different jobs.

    Clarity

  4. Fix what breaks worst first, not what I found first.

    Five concurrency defects, fixed deadlock first, with the headline speed fix held to last so the measurement could not flatter it.

    Semantic Search

  5. Write down what I chose not to build.

    Every case study carries the list. EaseMySemester's: no public signup, no ingestion pipeline, no paid tier.

    EaseMySemester

The lab

Tools with one user, and that user is me. They are where the method is easiest to check.

Everything in the lab

  • Wiki Pipeline

    Writes and checks the knowledge base behind this site every hour. One model drafts a page, a second with no tools grades it against the sources, and what passes is readable here.

    Decision
    Let it publish without me. A process that needs me every day is one I abandon, and an abandoned process still looks like it is working.
    Refused
    No remote on the repository and no hosting for the vault, and no attempt to have it write anything a reader sees. I write those.
    The caveat
    One user, running hourly since 14 September 2026. Separately, 0 of 204 harvested items got past the redaction scan.
    Still open
    Whether a checker that only ever sees a page and its sources can catch the failure I actually fear, which is a fact that was true the day it was written and quietly stopped being true. Matching a page to its source proves it was copied faithfully, not that the source is still the world.
    What it proves
    • An agent pipeline built as two roles that do not report to each other: a writer that drafts, and a checker with no tools that is given the sources inline so it cannot go looking for confirmation.
    • Hidden thinking treated as a product constraint with a measured cost, after one uncapped checker spent about 21,000 tokens to make 3 edits and a zero-capped one approved a page in 4 seconds.
    • A desktop app that is read only except for one cell, because applying and being rejected are things a person does, not things an agent can observe.

    200 pagesrewritten from my repos nightly, checked by a second model

  • Semantic Search

    The bench the other projects get measured on. Hybrid retrieval over my own textbooks, every run benchmarked and comparable, so a ranking change can be checked instead of argued about.

    Decision
    Measure first. The benchmark runner existed before a single retrieval setting had been tuned.
    Refused
    No sweeps across model combinations, no answer-quality scoring yet, and a locking issue filed rather than rushed into a change that had no room for it.
    The caveat
    The headline throughput fix went last on purpose, so the measurement could not flatter the fixes underneath it.
    Still open
    What good actually looks like. I can measure speed to the millisecond and answer quality not at all, which means every ranking decision I make here is currently unfalsifiable.
    What it proves
    • Building the measurement loop before tuning a single retrieval setting, so that every decision afterwards could be compared against something rather than argued about.
    • Root-causing a failure that presents as a bad model and is not: a 4,096-token context window quietly evicting the retrieved passages mid-generation.
    • Sequencing five concurrency defects by blast radius, deadlock first and the headline throughput fix last, so the measurement could not flatter the fixes underneath it.

    5 defectsfixed in blast-radius order

Before this

Three and a half years writing fund accounting software at Temenos, where I delivered the platform's first client go-live on IBOR: HSBC, 46 funds into production, later past 500. A product internship at Optum on a redesign that had to satisfy over 1,600 state and federal regulations. An MBA at IIT Kharagpur in between, and now enterprise sales.

What each role involved

  1. May 2025 to Present

    Hexaware Technologies

    Business Development Manager, New Logos

  2. May 2024 to Apr 2025

    Hexaware Technologies

    Senior Management Trainee, Hexaware Future Leaders

  3. 2023

    Optum

    Product Management Intern

  4. Jan 2019 to Jun 2022

    Temenos

    Development Intern → Software Engineer → Senior Software Engineer

“Adwitiya worked on one of the most critical projects at Temenos. His technical expertise combined with strong problem solving skills and passion for the product enabled him to close several complex issues.”
Nisha Mancheri, Vice President, Morgan Stanley. Previously senior to me at Temenos.

Most recent writing

I deleted the parts of Clarity I would have pitchedSelling to healthcare buyers taught me that a catalogue gets a nod and a named problem gets a conversation. Then I found the catalogue in my own product. 4 minEverything I have written

Write to me.

If any of this is useful to you, or wrong, I would like to hear it. Email is the fastest way to reach me.

Or connect on LinkedIn